MCP-Served Analytics as Load-Bearing Data Infrastructure for Agent-Native Product Teams
Agents making decisions from metrics need one governed definition layer behind MCP.
MCP-served analytics becomes load-bearing infrastructure when agents use metrics to make decisions without a human reviewing each step. For agent-native product teams, the central architectural requirement is a governed layer of pre-modeled metrics shared by agents, dashboards, and human workflows. MCP provides the access surface. Without a governed layer behind it, those consumers can quietly diverge in their business definitions.
Why MCP became infrastructure rather than a convenience feature
Anthropic introduced MCP in November 2024 and donated it to the Agentic AI Foundation under the Linux Foundation in December 2025. Native support across Claude, ChatGPT, Gemini, Microsoft Copilot, and Cursor established a shared integration surface across competing platforms. The protocol was no longer a platform-specific convenience. For product teams, that shift made the architecture behind an MCP endpoint a concern beyond any single agent integration.
The 2026-07-28 specification made the protocol core stateless by removing sessions and making each request self-describing. Any request can reach any instance behind a plain round-robin load balancer. Method and tool names also travel in HTTP headers, allowing gateways to route and authorize requests without parsing JSON bodies. This changes the access layer’s scaling model. It also raises the stakes of what that increasingly scalable infrastructure exposes.
What "load-bearing" means when agents are making decisions from your metrics
Analytics becomes load-bearing when the correctness of an agent’s decisions depends on the metrics the data layer supplies. A dashboard checked by a human leaves room for interpretation and correction before action. An agent pricing a customer tier, flagging churn risk, or generating an executive report can propagate an inconsistent definition without that review. The metric’s definition becomes a correctness constraint on the workflow.
One engineer writes SUM(revenue), another writes SUM(amount_captured), and an agent connected to raw tables creates a third interpretation. Without a semantic layer, all three can coexist. The CEO, CFO, and reporting agent may each produce a plausible revenue number, with no authoritative definition that resolves the disagreement.
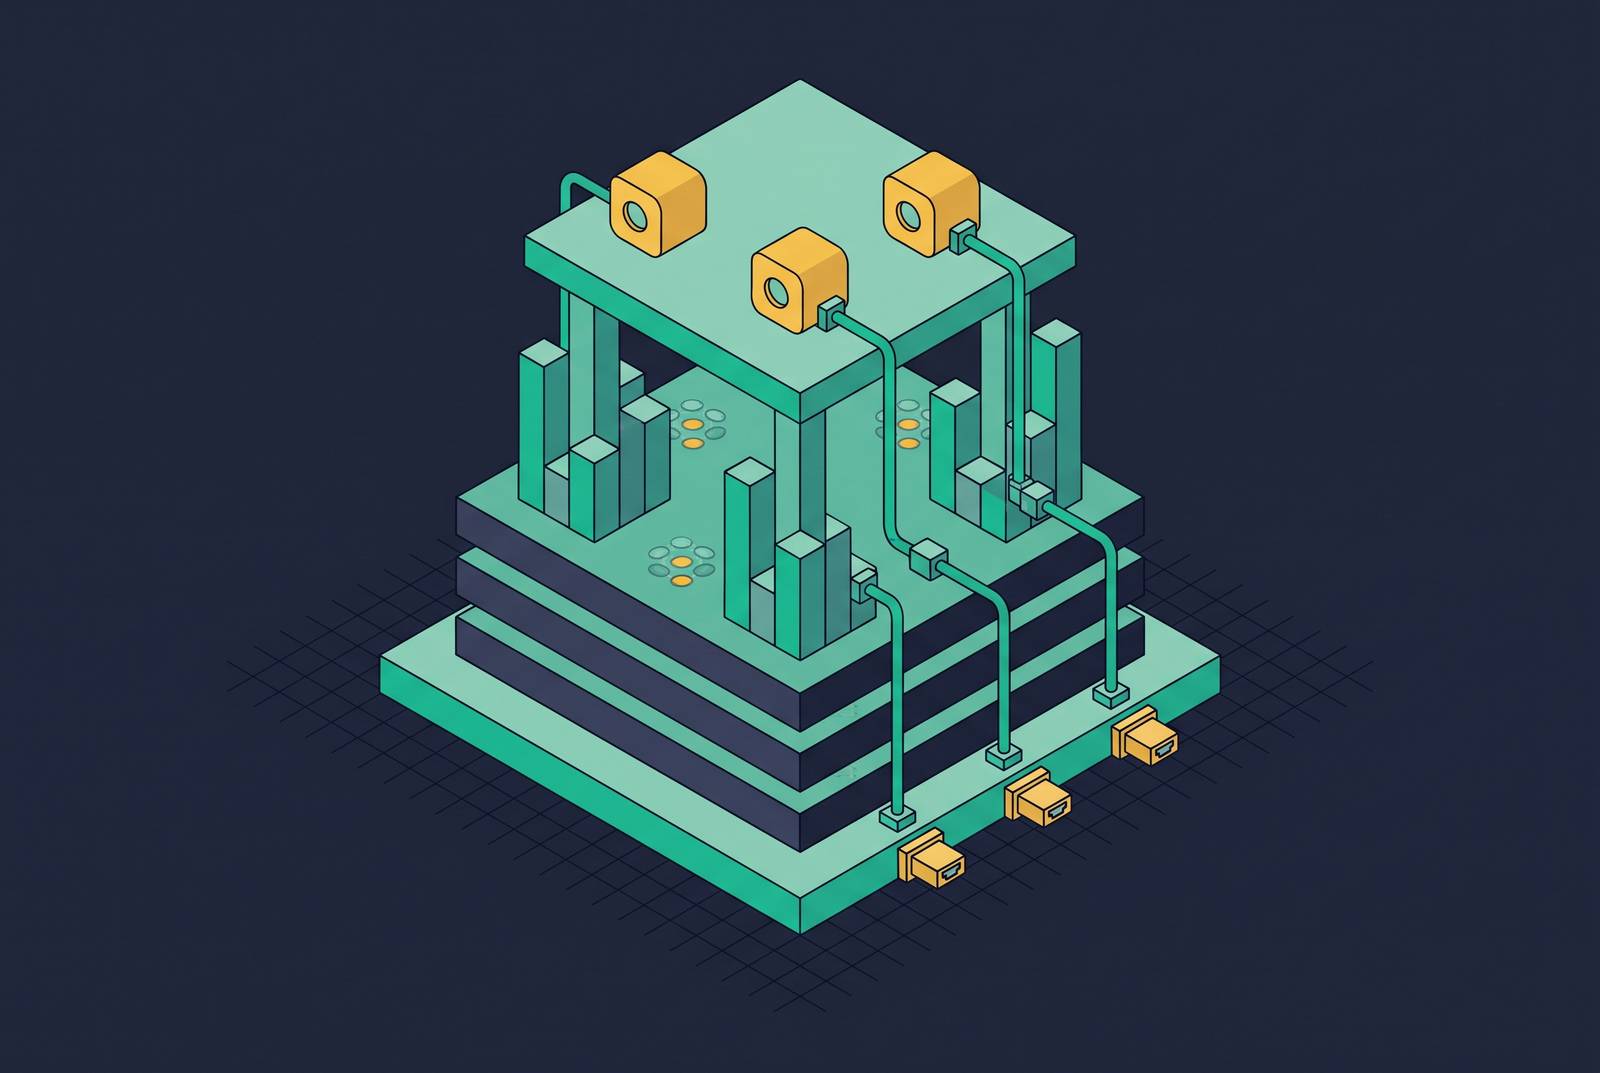
A four-layer architecture gives each responsibility a home. The Data Substrate holds verified, permissioned, refreshable data with documented provenance, while the Reasoning Layer holds semantic schemas and governed metric definitions. The Delivery Layer exposes those assets through MCP or an API. The Decision Layer is where an agent or human acts, with an owner and an outcome. Skipping the Reasoning Layer leaves delivery intact but meaning unconstrained.
How the three MCP primitives divide the analytical work
MCP’s Tools, Resources, and Prompts serve different analytical purposes. Tools run queries or start calculations, so they are a natural place to start for teams that want results they can see. Resources supply schemas, governed datasets, metric definitions, and documented provenance. Prompts encode reusable analytical workflows so agents do not reconstruct business logic on each call.
A Tool can retrieve a number, but Resources establish what that number represents, while Prompts guide its use in a repeatable calculation or workflow. Teams that expose only Tools leave those responsibilities unfilled. Without Resources and Prompts, the interface has an empty Reasoning Layer, leaving agents to decide for themselves what the data means.
The revised specification also supports more stable context and governed interaction. Its ttlMs and cacheScope fields make list responses cacheable, allowing clients to cache tool catalogs and keep upstream prompt caches stable. Caching does not itself define a metric. Separately, Multi Round-Trip Requests replace server-initiated requests with a client-retry pattern in which the server returns input_required when it needs additional input. That pattern lets analytical workflows include a step for human approval.
Why agents querying production Postgres directly is an architectural anti-pattern
For Supabase teams, direct Postgres access offers an apparently short path from an agent’s question to an answer. But Postgres is the source of truth for user data, auth tokens, Realtime channel metadata, and storage metadata. Analytical queries compete with those production responsibilities. Agents can exhaust connection pools, and adding stateless MCP instances does not remove that bottleneck. Protocol scalability is not database workload isolation.
Row-level security also makes the database harder to run. A policy that runs a team-members subquery for every row of a large query can create a database-level N+1 pattern. Wrapping auth.uid() as a scalar subquery lets the planner evaluate that expression once, but finding such problems requires instrumentation. Performance is only part of the concern. Direct agent access also risks bypassing RLS through access paths that are harder to audit than explicit permissions on a governed copy.
The architectural response is to separate analytical reads from transactional service. Metrics should be pre-calculated and materialized, then exposed through a governed, read-only MCP or API interface. Agents receive answers from prepared datasets rather than live transactional queries. This keeps analytical traffic away from the production instance while a consumer is waiting for an answer.
The governance gap that MCP adoption alone does not close
A standardized connection does not make its contents governed. Developers can use personal tokens to connect local MCP servers to production data while security has no record of those connections. Addressing them requires a registry of approved servers, agent identities tied to the organization’s identity provider, and a lightweight approval step.
The specification closes some protocol-level gaps through authorization hardening. It adds RFC 9207 issuer validation, formally deprecates Dynamic Client Registration in favor of Client ID Metadata Documents, and binds client credentials to their issuing authority. Enterprise Managed Authorization is a formal extension that adds SSO-integrated authentication and audit trails. These access controls cannot define revenue or establish that two agents using the same Tool name receive the same calculation.
Pinterest’s implementation illustrates the additional architectural choices required in production. It uses domain-specific MCP servers for data platforms, a central registry for discovery, and human-in-the-loop approval for high-risk operations. That architecture separates access from the production database and makes invocations auditable. The protocol provides the mechanisms, while the system around it sets where they apply and how they are enforced.
Headless analytics as the structural form that makes MCP-served metrics trustworthy
Headless analytics decouples analytical logic from any single front end and exposes it through MCP and API. Its defining feature is a backend that holds shared metric definitions and governed datasets. A dashboard, Slack message, or agent response then becomes a rendering choice rather than a separate opportunity to model the business.
When dashboards, internal reporting tools, and agents consume the same governed definition, their agreement no longer depends on each consumer independently reproducing business logic. The definition lives below the interface. Permissions and documented provenance belong to that shared data layer.
For Supabase teams, the proposed implementation makes “pre-modeled” operationally specific. Postgres remains the source of truth and change data capture engine, while metrics are pre-calculated and materialized into governed Parquet datasets queryable through DuckDB. A single MCP server exposes those datasets to agents and human interfaces. This pattern requires no ETL, schema changes, or separate warehouse. Because the Delivery Layer is independent of the Decision Layer, adding a human interface or agent workflow does not require remodeling the underlying metrics.
What metric governance has to look like for teams at different growth stages
Governance begins with a small canonical metric set. Before product-market fit, teams should keep that set to three to five metrics that cover activation, retention, and learning signals. Fewer definitions are easier to govern precisely. The purpose is to give both people and agents dependable signals rather than a broad collection of loosely specified dashboards.
After product-market fit through Series A, the core governed set for most B2B SaaS teams is CAC, LTV, monthly churn, ARR, and gross margin. Each can be calculated in more than one way that looks right. The semantic layer must specify the organization’s choices, including collected cash versus invoiced revenue and gross versus net churn where applicable. A familiar metric name is not a complete definition.
Delivery should reflect that same discipline. Metrics should be calculated ahead of time and pushed to inboxes, Slack, and mobile. Reporting agents need pre-modeled datasets to do that work the same way each time. Deferring the governed layer until Series B accumulates metric debt. The agent-era corollary is decisive, because a convention that a human resolves from context becomes a decision-making defect when it remains absent from the semantic layer.
What structural fragility actually looks like when analytics is treated as an afterthought
A churn report uses a different cohort definition from the retention dashboard, or a pricing recommendation uses revenue that excludes refunds. Neither output necessarily looks wrong in isolation. The inconsistency becomes visible only when the results are compared or a decision chain exposes the mismatch.
Shadow MCP servers make that pattern harder to diagnose. Each connection can use its own query logic, permission scopes, and metric calculations, so several unofficial sources of truth can grow side by side. At the same time, unrestricted production queries introduce unpredictable load. Connection-pool exhaustion is the visible symptom of that design. It may reveal the missing separation before anyone notices the semantic disagreement.
Supabase’s observability improvements lower the barrier to detecting these query patterns. Visibility helps, but it follows the connection. Observability can show the load agents generate after they receive access, whereas a governed analytical layer prevents that traffic from reaching production in the first place. It also addresses a different diagnostic question, namely which definition is authoritative. Query traces cannot supply a business definition that the architecture never encoded.
Building the governed MCP analytics layer on Supabase: the practical architecture
For a Supabase team implementing this pattern, the first step is workload separation. Operational queries remain on production Postgres, while analytical queries run against a governed copy containing pre-calculated metrics. That boundary must precede agent access to the datasets. Otherwise, the MCP server merely standardizes a route to the same transactional bottleneck.
The next step is to make definitions explicit. Each organizational metric needs one canonical definition in the semantic layer, exposed as a Resource or encoded in a Prompt so consumers receive the same calculation logic. Revenue, churn, and activation must have the same meaning for every caller. This connects the prepared Data Substrate to the Reasoning Layer rather than leaving agents to infer meaning from table names.
Agent identities should use the organization’s identity provider, and there should be a log of every invocation and a registry of approved servers. Production Postgres should not be reachable from agent traffic. Enterprise Managed Authorization and header-based routing provide protocol-level mechanisms for this design, but the data boundary remains an architectural responsibility.
Finally, delivery should use the same prepared datasets for scheduled reports and agent workflows. Governed metrics can reach Slack, inboxes, and dashboards without each destination issuing its own transactional query. The stateless core allows the MCP interface to scale horizontally like a REST API. New workflows can draw on additional governed datasets without redesigning the access layer. Growth then adds consumers to a shared analytical foundation instead of adding competing definitions of the business.