Why MCP Tool Schemas Beat a REST API Contract When Your Frontend Team Ships Its Own Analytics Surface
MCP schemas keep analytics consumers current, if the data layer is governed.
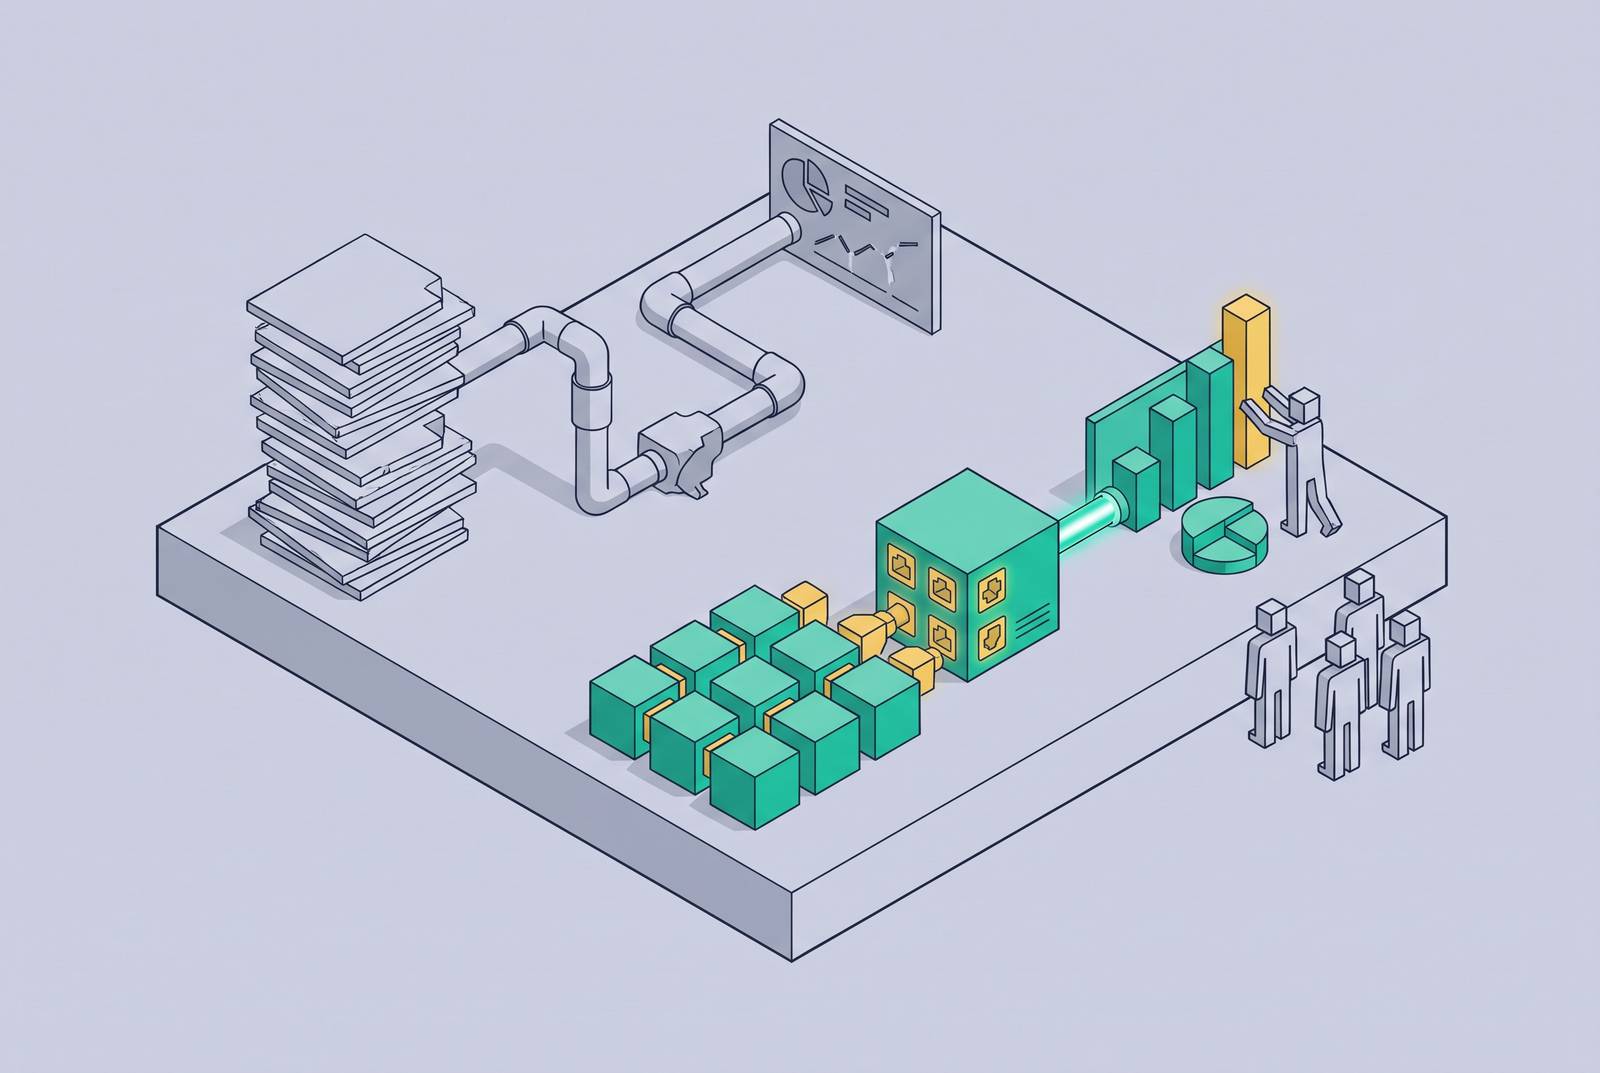
MCP tool schemas give frontend teams shipping analytics a better integration boundary because they describe what is available at runtime, so developers have no separate REST contract to maintain. That advantage depends on what sits behind the protocol. A governed data layer lets dashboards and agents use the same metric definitions, while a focused tool catalog keeps that shared interface easy to manage.
Why REST API contracts require a human in the loop
A plain REST API is like a locked cabinet. A developer must know which drawer to open and which key fits before the application can retrieve anything. Documentation supplies that knowledge, but the running client does not discover it for itself. The developer reads the contract, selects an endpoint, hardcodes arguments and error handling, and ships the calling code. From that point, the integration reflects what the developer understood at build time.
The coordination cost appears when the API changes. A human must interpret the change and update the client, because the application does not re-read the contract and adapt. A new consumer starts from the same external documentation rather than asking the service what capabilities it offers. A new chart, metric query or schema change can require the data team to update a specification, the frontend team to interpret it, and both teams to verify that their implementations agree.
What MCP tool schemas actually are and how runtime self-description works
An MCP server makes discovery part of the running interface. A client sends tools/list and gets machine-readable tool definitions that describe what it can use. Each definition has a name and an inputSchema, with other fields including an optional title, description and outputSchema. The client gets its contract from the service.
For a concrete analytics example, consider a tool for activation rate. Its name supplies the routing key, its description explains the metric, its inputSchema defines accepted arguments, and its outputSchema, when supplied, describes the result. For an agent, the description and property-level descriptions also become prompt content. They help the agent judge both whether the tool fits the user’s request and whether the request has the right shape.
The MCP tools specification states the control model plainly. “Tools in MCP are designed to be model-controlled, meaning that the language model can discover and invoke tools automatically based on its contextual understanding and the user's prompts”. A compatible client can discover a newly exposed tool without bespoke integration code for that capability. This does not mean that discovery designs a new chart or rewrites a custom frontend automatically.
MCP therefore changes the consumer boundary while retaining the API underneath. An MCP server can call REST internally while exposing capabilities that an agent can reason about without a separate specification. Standardizing that boundary also reduces the M×N connector problem to M+N, because each model and tool integrates with the shared protocol. For analytics, however, the strongest benefit is keeping consumers attached to the current meaning and shape of their data.
Why analytics surfaces specifically benefit from runtime schema discovery
Analytics interfaces are especially prone to trouble from changes that are still technically valid. A renamed dimension can break a query, but a redefined metric can leave the query running while changing what its result means. That is the harder failure to detect. A dashboard and a board deck can show different numbers without either system reporting an error, because both requests still give results that look right.
The inventory example illustrates this risk through eleven days of silent degradation. The parallel for an analytics surface is a metric whose meaning changes while the integration contract remains untouched. The frontend continues to receive an answer, so a successful response offers no assurance that the answer still represents the intended measure. Runtime discovery shortens this gap by making updated definitions available to consumers on their next connection rather than waiting for a manual specification handoff.
MCP tool schemas support pre-execution validation through JSON Schema, allowing validation to detect malformed arguments before the query runs. For analytics, this is a data-integrity control. A bad argument should not become a plausible but incorrect metric buried in a successful response.
That protection has a clear boundary. Validation can reject an argument that violates the declared schema, but it cannot make an incorrectly defined metric true. Similarly, runtime discovery exposes the definition that the server publishes, leaving its correctness to be judged independently. Analytics therefore benefits from self-description only when the published descriptions and metric definitions are governed together.
The governance implication: tool schema fields that look like documentation are actually behavioral contracts
Runtime self-description removes a manual handoff but calls for more care with change control. In a conventional OpenAPI workflow, prose largely explains the typed contract to developers. In an MCP tool definition, prose can directly shape what the caller decides to do. Rewording a description may change tool selection without changing any type. Error text has similar force because it guides what an agent tries next.
That inversion is easy to underestimate during development. A team that would require a deprecation window before renaming a public REST field may rename a tool argument because it expects the agent to infer the change. The agent may adapt, but it may also drop the argument and report success. Flexibility is not a substitute for compatibility. The behavioral contract includes the language around the schema as well as the schema itself.
SEP-2106 demonstrates why compatibility needs a precise definition. The proposal widened structuredContent from { [key: string]: unknown } to unknown, describing the change as “a source-breaking change for typed consumers, even though the wire format is unchanged.” An unchanged transmission format does not guarantee an unchanged consumer experience. The same distinction applies when an analytics tool changes what its arguments or returned values mean.
The practical response is to treat metric definitions as code, with versioned and auditable changes. The Philadelphia Inquirer adopted this posture around 2024–2025 through its dbt Semantic Layer and version-controlled metrics-as-code governance model. That example establishes an achievable operating practice rather than a requirement to invent a new governance system. Under this model, a metric’s definition is maintained as a shared asset.
Caching introduces another contract boundary. The 2026-07-28 MCP specification revision added ttlMs and cacheScope to list results to state how long they stay fresh and whether shared intermediaries may cache a response as public or private. Those fields help manage repeated discovery requests. They also mean that cached consumers may not see a tool change within the declared freshness window, so runtime discovery should not be confused with instantaneous propagation.
What the governed data layer behind the MCP server must look like
A discoverable interface cannot repair an unreliable dataset. The backend therefore needs distinct responsibilities for data, meaning, delivery and decisions. Each responsibility protects a different part of the path from source data to an actionable metric.
The data substrate holds verified, permissioned, refreshable data with documented provenance. Above it, a reasoning layer supplies semantic schemas and metric definitions, while a delivery layer exposes those capabilities through the MCP endpoint. A decision layer connects the resulting intelligence to an owner and an outcome. The separation is deliberate. The tool definition should describe a governed capability, rather than conceal unresolved questions about where its data came from or what its result means.
For this architecture, agents should not query the production database through the MCP server. A governed analytical copy with pre-calculated datasets allows queries without putting connection-pool pressure on transactional workloads. Direct access to production Postgres instead inherits RLS friction, pooler limits and analytical load on OLTP compute. Materializing metrics ahead of time keeps that analytical work away from the transactional database while a consumer waits for an answer.
Supabase teams also need to distinguish database visibility from application context. The Supabase Metrics API exposes Postgres performance and health metrics in Prometheus exposition format, but those metrics are bounded by what Supabase can see. They cannot explain that a particular user action triggered a slow query or that an edge function timeout caused a cascade of errors. Distributed tracing across the full stack supplies that context. Neither database monitoring nor a discoverable tool catalog substitutes for the governed analytics layer above them.
Enterprise implementations show the same separation of capability from interface. Informatica went fully headless at Informatica World 2026, decoupling core IDMC capabilities from its graphical interface and exposing them as microservices through MCP endpoints. Salesforce’s Data 360 MCP Server likewise exposes Data 360 APIs through an MCP surface rather than making MCP synonymous with raw database access. Even with that foundation, making every tool available adds a cost to running the system.
The token-cost trade-off and why a tightly scoped tool catalog is the right design discipline
Tool definitions consume model context as well as describe capabilities. A broad catalog repeatedly introduces names, descriptions and schemas that may have no role in the current task. REST callers do not incur that same prompt cost simply to invoke an endpoint. For an agent-driven analytics surface, the relevant design question is therefore how much capability information each turn actually needs.
Defining each metric once in code and exposing a tool per governed metric gives the model a smaller set of meaningful choices. The catalog can offer MRR, activation rate and churn in place of every column in every table. Fewer irrelevant definitions reduce schema token consumption.
A one-to-one wrapper around an existing API works against that discipline. It transfers the API’s breadth into the model’s context, whether or not that breadth helps answer the user’s question. The resulting context rot comes from surrounding the task with unnecessary information.
Caching helps with repeated schema reads, but it does not make an oversized catalog well designed. The freshness controls govern reuse, while catalog scope governs what the consumer must understand in the first place. A lean surface keeps both the prompt burden and the set of behavioral contracts under control.
This leaves REST with a clear role underneath MCP. Applications that send frequent requests can keep them off the capability layer built for models, even when analytics agents use that layer. The design is a narrower discovery interface over an API and data substrate chosen for their respective workloads.
What this architecture means for a frontend team shipping analytics today
For a frontend team, the operational shift begins with how a chart gets its data. The team first discovers whether a governed tool for the metric already exists through tools/list, rather than assuming that a new endpoint and documentation handoff are required. If the capability exists, the work can remain focused on presenting it. A genuinely new metric still needs a definition, but an existing one does not need another separately maintained integration contract.
Changes to that definition also follow a different path. If the data layer changes how activation is calculated and publishes the corresponding tool definition, consumers can discover the updated description and output schema on their next connection, subject to caching. The dashboard and agent read from the same governed interface. Custom presentation logic may still require work when a result shape changes, but the frontend team no longer has to learn about the change solely through an external specification.
That shared metric layer should be established before expanding the tool surface. For Supabase teams, the proposed architecture combines pre-calculated metrics, governed Parquet datasets queryable through DuckDB, and a single MCP server. Database observability and full-stack tracing are still needed in their own right. The analytical copy gives agents access to useful context without directing their queries at production Postgres.
The final responsibility is ownership of meaning. When the CEO, CFO and product team call the same named revenue metric, their applications no longer need independent definitions of that measure. MCP makes the shared definition discoverable, while governance makes it authoritative. The frontend team gains room to change the analytics experience without also becoming the maintainer of a second account of what the data means.